You can synchronise metadata from K to Databricks using K metadata extracts and Databricks native jobs to process the extracts.
The out of the box configuration will sync for Tables & Column:
-
Description
-
Term
-
Category
-
Classification
-
Domain
-
Owner
-
Steward
-
PII Data Detected
These can be adjusted or expanded per your requirements.
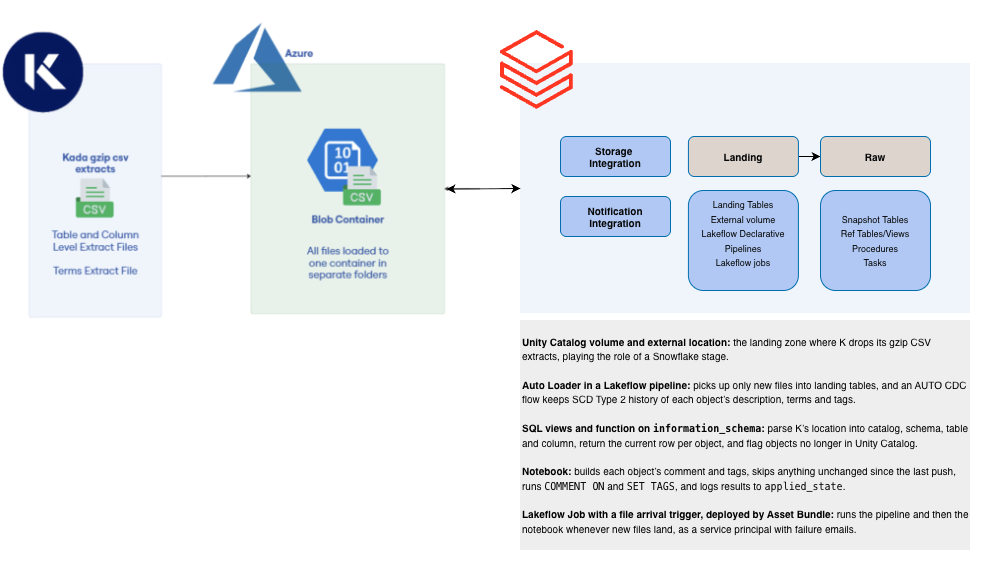
The following are the components that we will use to implement the automated sync between Kada and Databricks.
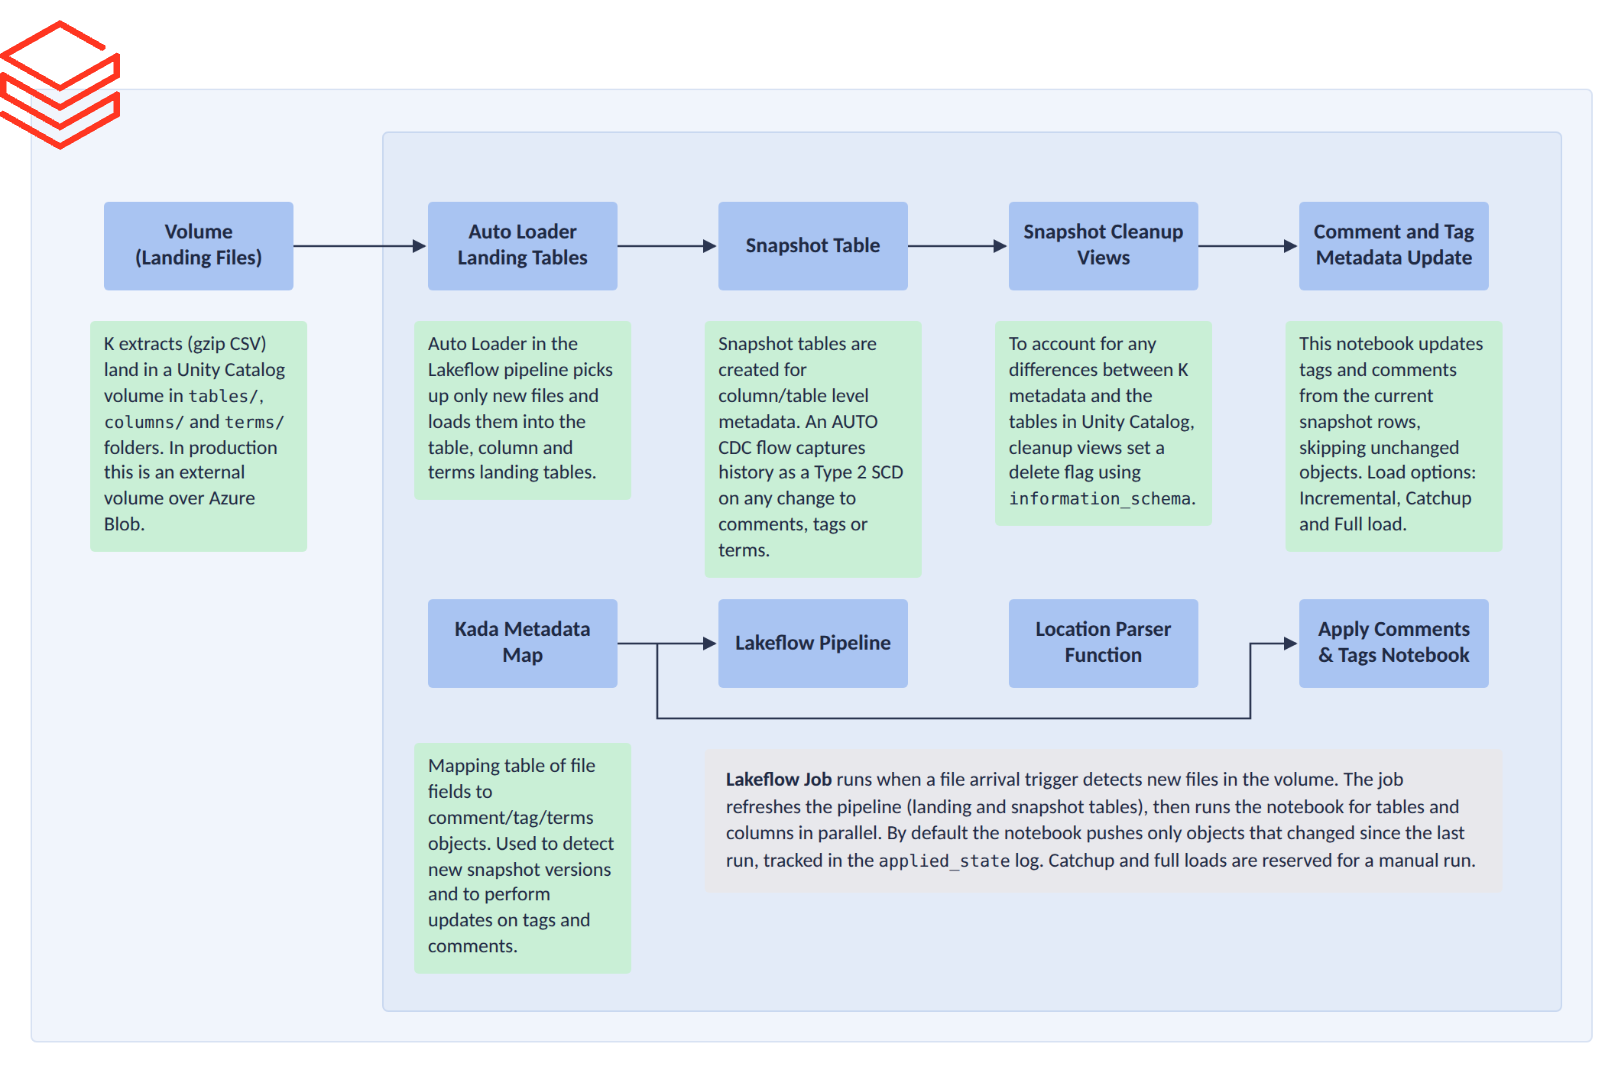
The following provides an overview of the process.
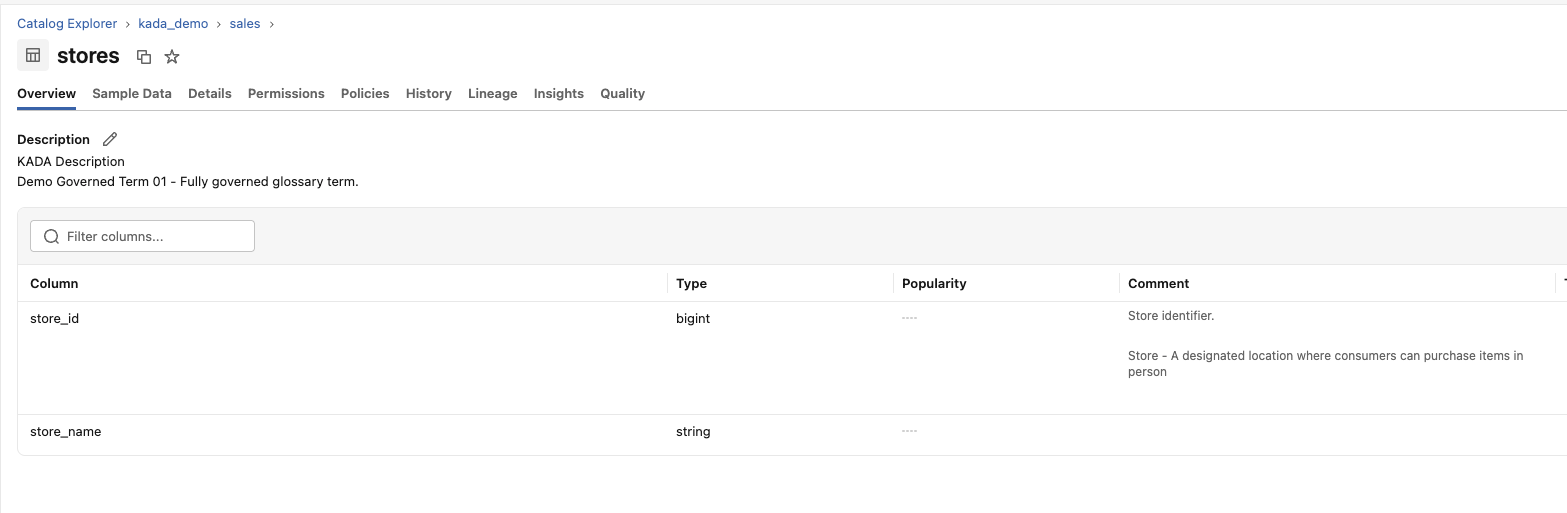
Once the sync is configured, Databricks assets will be updated with descriptions, terms and governance attributes
Guides
-
Configure storage accounts for K metadata files to Databricks
-
The files delivered to the storage accounts will be loaded to Databricks using Auto loader
-
-
Configure the Metadata Sync files (Same as Sync to Snowflake)