New in Version 6.1
The following provides details on how to configure an automated sync mechanism to sync K descriptions, terms and governance details as comments and tags to Snowflake assets.
Prerequisites
-
Configure metadata sync files for
-
Snowflake Tables
-
Snowflake Columns (for Tables and Views)
-
Terms
-
-
Configure Storage accounts for each environment
-
Configure each sync file to be delivered to the Storage account
Configuring Snowflake
DATABASE SETUP
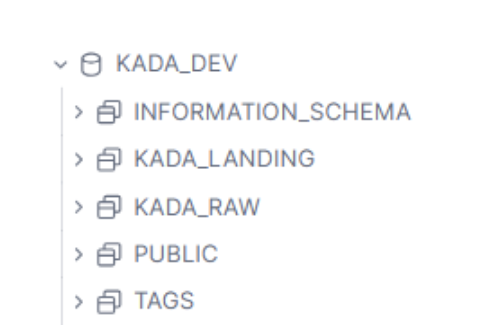
Using SYSADMIN, create databases for each environment DEV/UAT/PROD that you want to sync metadata for. For example if you only want to sync metadata for Production assets, setup a KADA_PROD database.
A dev sync is recommended to confirm the comments & tags are being updated as expected
The naming convention for the database is KADA_<Env>. For example
-
KADA_DEV
-
KADA_UAT
-
KADA_PROD
For each of the database, create the following schemas in each database:
-
KADA_LANDING
-
KADA_RAW
-
TAGS
Optional: Grant any additional role access as required to the databases, schemas and any underlying objects (tables, streams, procedures etc) for any roles that need access to the Kada metadata
METADATA TABLE SETUP
The following provides the DDLs for each control table to be created in snowflake.
Snowpipe & Snapshot Tables
Note: Schema evolution is set for snowpipe landing tables and only the snowpipe metadata columns are created as a starting point. Once a file is ingested, the table will be built out with the columns received from the file.
--TABLE LEVEL (SNOWPIPE LANDING)
create or replace TABLE KADA_DEV.KADA_LANDING.KADA_TBL_METADATA (
	FILE_NAME VARCHAR(16777216),
	FILE_ROW_NUMBER NUMBER(38,0),
	FILE_LAST_MODIFIED TIMESTAMP_NTZ(9),
    START_SCAN_TIME TIMESTAMP_TZ
)
ENABLE_SCHEMA_EVOLUTION = TRUE
COMMENT='Used for loading table level metadata via copy into';


--COLUMN LEVEL (SNOWPIPE LANDING)
CREATE OR REPLACE TABLE KADA_DEV.KADA_LANDING.KADA_COL_METADATA (
	FILE_NAME VARCHAR(16777216),
	FILE_ROW_NUMBER NUMBER(38,0),
	FILE_LAST_MODIFIED TIMESTAMP_NTZ(9),
    START_SCAN_TIME TIMESTAMP_TZ
)
ENABLE_SCHEMA_EVOLUTION = TRUE
COMMENT='Used for loading column level metadata via copy into';

--TERMS DATA (SNOWPIPE LANDING)
create or replace TABLE KADA_DEV.KADA_LANDING.KADA_TERM_METADATA (
	FILE_NAME VARCHAR(16777216),
	FILE_ROW_NUMBER NUMBER(38,0),
	FILE_LAST_MODIFIED TIMESTAMP_NTZ(9),
    START_SCAN_TIME TIMESTAMP_TZ
)
ENABLE_SCHEMA_EVOLUTION = TRUE
COMMENT='Used for loading terms metadata via copy into'
;

--TABLE LEVEL (SNAPSHOT)
CREATE OR REPLACE TABLE KADA_DEV.KADA_RAW.KADA_TBL_METADATA_SNAP (
    SNAP_ID VARCHAR(16777216),
	FILE_NAME VARCHAR(16777216),
	FILE_ROW_NUMBER NUMBER(38,0),
	FILE_LAST_MODIFIED TIMESTAMP_NTZ(9),
    START_SCAN_TIME TIMESTAMP_TZ,
    NAME VARCHAR(16777216),
    LOCATION VARCHAR(16777216),
    ASSET VARCHAR(16777216),
    CHANGE_STATUS VARCHAR(16777216),
    ASSET_SUBTYPE VARCHAR(16777216),
    BUSINESS_NAME VARCHAR(16777216),
    COLLECTION_TYPE VARCHAR(16777216),
    COLLECTION VARCHAR(16777216),
    EXTERNAL_URL VARCHAR(16777216),
    ID VARCHAR(16777216),
    DESCRIPTION VARCHAR(16777216),
    COLLECTION_CATEGORY VARCHAR(16777216),
    COLLECTION_CLASSIFICATION VARCHAR(16777216),
    COLLECTION_DOMAIN VARCHAR(16777216),
    TRUST VARCHAR(16777216),
    OWNERS VARCHAR(16777216),
    STEWARDS VARCHAR(16777216),
    COLLECTION_PII_DATA_DET VARCHAR(16777216),
    TERMS VARCHAR(16777216),
    ROW_CHECK_FINGERPRINT VARCHAR(16777216),
	SNAP_SCD_ID VARCHAR(32),
	SNAP_UPDATED_AT TIMESTAMP_NTZ(9),
	SNAP_VALID_FROM TIMESTAMP_NTZ(9),
	SNAP_VALID_TO TIMESTAMP_NTZ(9),
    OBJ_TYPE VARCHAR(16777216),
    IS_OBJ_NAME VARCHAR(16777216),
    UPDATE_FLAG VARCHAR(16777216),
    DELETE_FLAG VARCHAR(16777216)
)COMMENT='Snapshot table for Table Metadata';


--COLUMN LEVEL SNAPSHOT (SNAPSHOT)
CREATE OR REPLACE TABLE KADA_DEV.KADA_RAW.KADA_COL_METADATA_SNAP (
    SNAP_ID VARCHAR(16777216),
	FILE_NAME VARCHAR(16777216),
	FILE_ROW_NUMBER NUMBER(38,0),
	FILE_LAST_MODIFIED TIMESTAMP_NTZ(9),
    START_SCAN_TIME TIMESTAMP_TZ,
    NAME VARCHAR(16777216),
    LOCATION VARCHAR(16777216),
    ASSET VARCHAR(16777216),
    CHANGE_STATUS VARCHAR(16777216),
    ASSET_SUBTYPE VARCHAR(16777216),
    BUSINESS_NAME VARCHAR(16777216),
    COLLECTION_TYPE VARCHAR(16777216),
    COLLECTION VARCHAR(16777216),
    EXTERNAL_URL VARCHAR(16777216),
    ID VARCHAR(16777216),
    DESCRIPTION VARCHAR(16777216),
    COLLECTION_CATEGORY VARCHAR(16777216),
    COLLECTION_CLASSIFICATION VARCHAR(16777216),
    COLLECTION_DOMAIN VARCHAR(16777216),
    TRUST VARCHAR(16777216),
    OWNERS VARCHAR(16777216),
    STEWARDS VARCHAR(16777216),
    TERMS VARCHAR(16777216),
    COLLECTION_PII_DATA_DET VARCHAR(16777216),
    ROW_CHECK_FINGERPRINT VARCHAR(16777216),
	SNAP_SCD_ID VARCHAR(32),
	SNAP_UPDATED_AT TIMESTAMP_NTZ(9),
	SNAP_VALID_FROM TIMESTAMP_NTZ(9),
	SNAP_VALID_TO TIMESTAMP_NTZ(9),
    OBJ_TYPE VARCHAR(16777216),
    IS_OBJ_NAME VARCHAR(16777216),
    UPDATE_FLAG VARCHAR(16777216),
    DELETE_FLAG VARCHAR(16777216)
)COMMENT='Snapshot table for Column Metadata';

--TAG/COMMENT MASTER TABLE
CREATE OR REPLACE TABLE KADA_DEV.KADA_RAW.KADA_METADATA (
	FILE_COLUMN_NAME VARCHAR(16777216),
	METADATA_NAME VARCHAR(16777216),
    METADATA_TYPE VARCHAR(16777216),
    METADATA_OBJ_LEVEL VARCHAR(16777216)
)COMMENT='Table for Kada Master Metadata';
For the SNAPSHOT tables, only create these tables once the file structure has been finalised (this may vary to the ddl provided above). The column names in the snapshot table should match those of the incoming files loaded to their respective Snowpipe landing tables.
WARNING: Make sure the Snapshot table structure in the DDL matches the Kada template generated
The Snowpipe landing tables can first be created including associated integrations for Snowpipe ingestion. With Snowpipe running and tested, create the snapshot tables can then be created based on the structures ingested.
Note: Additional snapshot specific columns are to be included that are not file specific (SNAP_ID, ROW_CHECK_FINGERPRINT, SNAP_SCD_ID, SNAP_UPDATED_AT, SNAP_VALID_FROM, SNAP_VALID_TO, OBJ_TYPE, IS_OBJ_NAME,UPDATE_FLAG, DELETE_FLAG).
Kada Control Table
The KADA_METADATA table is a control table. It is a manually maintained table that provides the mappings between file field columns to tag/comment/terms.
Ensure all 3 metadata types are included in this file
-
TAG
-
COMMENT
-
TERMS
These are used to determine what gets triggered in the snapshot to create a new record.
-
E.g. If there is any value change with incoming files from the list of columns in this table, a snapshot record is triggered. This is also used for tag / comment updates.
The Object Level (TBL/COL) is included so that different tags can be applied at different levels.
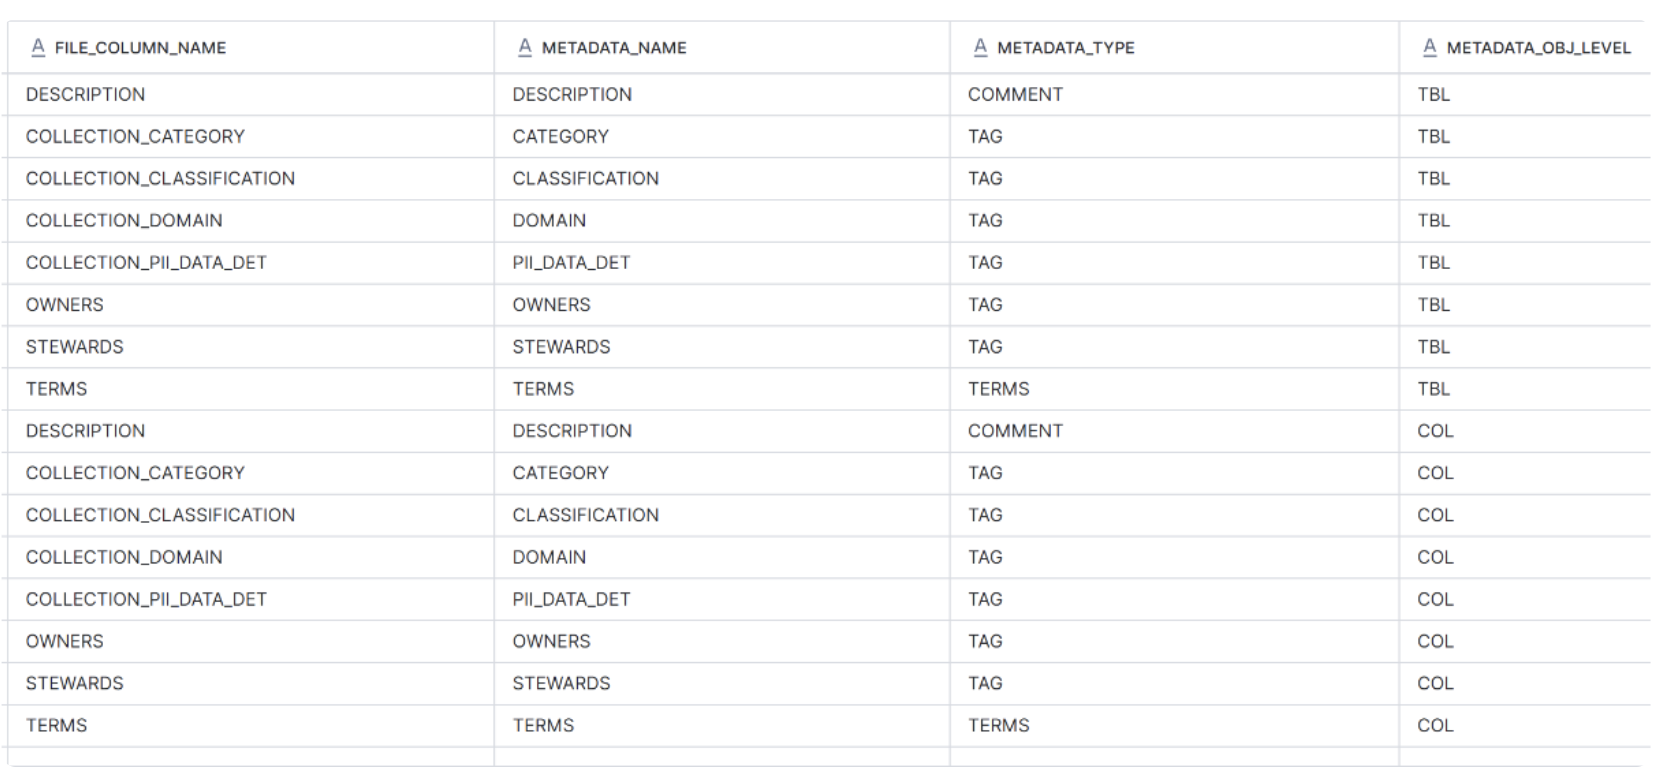
You can use this insert statement to populate the KADA_METADATA table with default values (matches the snapshot tables above).
INSERT INTO KADA_DEV.KADA_RAW.KADA_METADATA (FILE_COLUMN_NAME, METADATA_NAME, METADATA_TYPE, METADATA_OBJ_LEVEL)
VALUES
('DESCRIPTION', 'DESCRIPTION', 'COMMENT', 'TBL'),
('COLLECTION_CATEGORY', 'CATEGORY', 'TAG', 'TBL'),
('COLLECTION_CLASSIFICATION', 'CLASSIFICATION', 'TAG', 'TBL'),
('COLLECTION_DOMAIN', 'DOMAIN', 'TAG', 'TBL'),
('COLLECTION_PII_DATA_DET', 'PII_DATA_DET', 'TAG', 'TBL'),
('OWNERS', 'OWNERS', 'TAG', 'TBL'),
('STEWARDS', 'STEWARDS', 'TAG', 'TBL'),
('TERMS', 'TERMS', 'TERMS', 'TBL'),
('DESCRIPTION', 'DESCRIPTION', 'COMMENT', 'COL'),
('COLLECTION_CATEGORY', 'CATEGORY', 'TAG', 'COL'),
('COLLECTION_CLASSIFICATION', 'CLASSIFICATION', 'TAG', 'COL'),
('COLLECTION_DOMAIN', 'DOMAIN', 'TAG', 'COL'),
('COLLECTION_PII_DATA_DET', 'PII_DATA_DET', 'TAG', 'COL'),
('OWNERS', 'OWNERS', 'TAG', 'COL'),
('STEWARDS', 'STEWARDS', 'TAG', 'COL'),
('TERMS', 'TERMS', 'TERMS', 'COL');
The code will populate the Control table like so:
FILE INGESTION SETUP
Note: The following instructions are for Azure storage. Follow the Snowflake instructions to configure AWS and other storage options.
STORAGE INTEGRATION
Create a storage integration.
If all storage accounts have been created (dev/uat/prod), these can all be included in the allowed locations.
CREATE STORAGE INTEGRATION KADA_STORAGE_INTEGRATION
  TYPE = EXTERNAL_STAGE
  STORAGE_PROVIDER = 'AZURE'
  ENABLED = TRUE
  AZURE_TENANT_ID = '<tenant id>'
  STORAGE_ALLOWED_LOCATIONS = ('azure://kadadev.blob.core.windows.net/snowflake-metadata/','azure://kadauat.blob.core.windows.net/snowflake-metadata/','azure://kadaprod.blob.core.windows.net/snowflake-metadata/');

GRANT USAGE ON INTEGRATION KADA_STORAGE_INTEGRATION TO ROLE SYSADMIN;

DESC STORAGE INTEGRATION KADA_STORAGE_INTEGRATION;
Run the Describe on the storage integration to pick up the service principal and consent URL and grant access to the storage account.
FILE FORMAT
Create a file format for use in the snowpipe
CREATE OR REPLACE FILE FORMAT KADA_DEV.KADA_LANDING.KADA_CSV_METADATA_FILE_FORMAT
TYPE = CSV
PARSE_HEADER = TRUE
ERROR_ON_COLUMN_COUNT_MISMATCH = FALSE
FIELD_OPTIONALLY_ENCLOSED_BY ='"'
EMPTY_FIELD_AS_NULL = TRUE
TRIM_SPACE = TRUE
NULL_IF = ('', '""', 'NULL', 'null', 'Null');
STAGE
Create a stage using the storage integration
CREATE STAGE KADA_DEV.KADA_LANDING.KADA_METADATA_STAGE
STORAGE_INTEGRATION = KADA_STORAGE_INTEGRATION
URL = 'azure://kadadev.blob.core.windows.net/snowflake-metadata/'
file_format = (TYPE=CSV);
NOTIFICATION INTEGRATION
Ensure a queue has been created in the storage account and an event has been set up.
Note: Ensure service principal has the “Storage Queue Data Contributor” role assigned.
create notification integration KADA_METADATA_NOTIFICATION_DEV
enabled = true
type = queue
notification_provider = azure_storage_queue
azure_storage_queue_primary_uri = 'https://kadadev.queue.core.windows.net/kadadevqueue'
azure_tenant_id = '<tenant id>';

DESC NOTIFICATION INTEGRATION KADA_METADATA_NOTIFICATION_DEV;
SNOWPIPE
Create Snowpipes for the column level, table level and terms ingestion. These Snowpipes allow for schema evolution.
CREATE PIPE KADA_DEV.KADA_LANDING.KADA_TBL_METADATA_PIPE
auto_ingest = true
integration = 'KADA_METADATA_NOTIFICATION_DEV'
as
COPY INTO KADA_DEV.KADA_LANDING.KADA_TBL_METADATA
FROM @KADA_DEV.KADA_LANDING.KADA_METADATA_STAGE
FILE_FORMAT = (FORMAT_NAME = 'KADA_DEV.KADA_LANDING.KADA_CSV_METADATA_FILE_FORMAT')
PATTERN ='.*_table.*.csv.gz'
MATCH_BY_COLUMN_NAME = CASE_INSENSITIVE
ON_ERROR = SKIP_FILE
INCLUDE_METADATA = (
    FILE_NAME = METADATA$FILENAME,
    FILE_ROW_NUMBER = METADATA$FILE_ROW_NUMBER,
    FILE_LAST_MODIFIED = METADATA$FILE_LAST_MODIFIED,
    START_SCAN_TIME = METADATA$START_SCAN_TIME
);

CREATE PIPE KADA_DEV.KADA_LANDING.KADA_COL_METADATA_PIPE
auto_ingest = true
integration = 'KADA_METADATA_NOTIFICATION_DEV'
as
COPY INTO KADA_DEV.KADA_LANDING.KADA_COL_METADATA
FROM @KADA_DEV.KADA_LANDING.KADA_METADATA_STAGE
FILE_FORMAT = (FORMAT_NAME = 'KADA_DEV.KADA_LANDING.KADA_CSV_METADATA_FILE_FORMAT')
PATTERN ='.*_column.*.csv.gz'
MATCH_BY_COLUMN_NAME = CASE_INSENSITIVE
ON_ERROR = SKIP_FILE
INCLUDE_METADATA = (
    FILE_NAME = METADATA$FILENAME,
    FILE_ROW_NUMBER = METADATA$FILE_ROW_NUMBER,
    FILE_LAST_MODIFIED = METADATA$FILE_LAST_MODIFIED,
    START_SCAN_TIME = METADATA$START_SCAN_TIME
);

CREATE PIPE KADA_DEV.KADA_LANDING.KADA_TERM_METADATA_PIPE
auto_ingest = true
integration = 'KADA_METADATA_NOTIFICATION_DEV'
as
COPY INTO KADA_DEV.KADA_LANDING.KADA_TERM_METADATA
FROM @KADA_DEV.KADA_LANDING.KADA_METADATA_STAGE
FILE_FORMAT = (FORMAT_NAME = 'KADA_DEV.KADA_LANDING.KADA_CSV_METADATA_FILE_FORMAT')
PATTERN ='.*_term.*.csv.gz'
MATCH_BY_COLUMN_NAME = CASE_INSENSITIVE
ON_ERROR = SKIP_FILE
INCLUDE_METADATA = (
    FILE_NAME = METADATA$FILENAME,
    FILE_ROW_NUMBER = METADATA$FILE_ROW_NUMBER,
    FILE_LAST_MODIFIED = METADATA$FILE_LAST_MODIFIED,
    START_SCAN_TIME = METADATA$START_SCAN_TIME
);

--example to test pipe status
select system$pipe_status('KADA_DEV.KADA_LANDING.KADA_TBL_METADATA_PIPE');

--example to check copy history
SELECT * FROM TABLE(KADA_DEV.INFORMATION_SCHEMA.COPY_HISTORY(
TABLE_NAME => 'KADA_DEV.KADA_LANDING.KADA_TBL_METADATA',
START_TIME => DATEADD(hours, -1, CURRENT_TIMESTAMP())
));
STREAMS
Streams are created to only consume incoming new records from the Snowpipe landing tables. These are then subsequently consumed by the procedure to populate the snapshot tables. Streams can handle new columns added to the base tables, so these can be created prior to the snowpipe tables getting built out with schema evolution.
The streams are also used as the trigger to kick off the Synchronisation TASK.
CREATE OR REPLACE STREAM KADA_DEV.KADA_LANDING.KADA_COL_METADATA_STREAM ON TABLE KADA_DEV.KADA_LANDING.KADA_COL_METADATA;

CREATE OR REPLACE STREAM KADA_DEV.KADA_LANDING.KADA_TBL_METADATA_STREAM ON TABLE KADA_DEV.KADA_LANDING.KADA_TBL_METADATA;

--for testing purposes if you need to clear out the stream data, these can be flushed by running a dummy insert to consume the data

INSERT INTO KADA_DEV.KADA_LANDING.KADA_TBL_METADATA(LOCATION)
SELECT LOCATION FROM KADA_DEV.KADA_LANDING.KADA_TBL_METADATA_STREAM WHERE 1 = 0;

INSERT INTO KADA_DEV.KADA_LANDING.KADA_COL_METADATA(LOCATION)
SELECT LOCATION FROM KADA_DEV.KADA_LANDING.KADA_COL_METADATA_STREAM WHERE 1 = 0;
PROCEDURES
ROLES
In order for tags and comments to be updated on a table or view, the role executing the procedure needs to either be the owner of the table/view or needs to be granted to the role of the table/view owner.
In granting the executing role to the role of the table/view owner, the executing role inherits the owner privileges and allows tags / comments to be updated.
There is an account level setting for tags to enable altering across all tables regardless of ownership:
GRANT APPLY TAG ON ACCOUNT TO ROLE <custom_role>;
Note: There is currently no account level setting to enable altering comments across all tables regardless of ownership.
CREATE_DROP_TAGS
The following procedure provides the ability to create or drop tags.
This procedure is run manually to create the required tags as part of this solution.
These tags should match the naming convention as set in the KADA_METADATA table (METADATA_NAME column)
Note: Before a tag can be dropped, all tag references must first be Unset.
CREATE OR REPLACE PROCEDURE KADA_DEV.KADA_RAW.CREATE_DROP_TAGS(
    action STRING, --set to CREATE or DROP
    tag_list ARRAY
)
RETURNS TABLE()
LANGUAGE SQL
AS
$$
DECLARE
    res_tag RESULTSET;
    tag_stmt VARCHAR;
    tag_schema VARCHAR;


BEGIN

    tag_schema := CURRENT_DATABASE() || '.TAGS';

    res_tag := (

        SELECT
            :tag_schema || '.' || VALUE AS TAG,
            'CREATE TAG IF NOT EXISTS ' || TAG ||'' AS CREATE_TAG,
            'DROP TAG IF EXISTS ' || TAG ||'' AS DROP_TAG
        FROM TABLE(FLATTEN(INPUT => :tag_list))

    );


    FOR tag_record IN res_tag DO

        IF (UPPER(:action) = 'CREATE') THEN
            tag_stmt := tag_record.CREATE_TAG;
        ELSEIF (UPPER(:action) = 'DROP') THEN
            tag_stmt := tag_record.DROP_TAG;
        ELSE
            tag_stmt := 'SELECT 1';
        END IF;

        ASYNC (EXECUTE IMMEDIATE :tag_stmt);

    END FOR;

    AWAIT ALL;


  RETURN TABLE(res_tag);

END;
$$;
Setting up the default tags
Use the following code to create all default tags
call KADA_DEV.KADA_RAW.CREATE_DROP_TAGS(
'CREATE',
['CATEGORY','CLASSIFICATION', 'DOMAIN', 'OWNERS', 'STEWARDS', 'PII_DATA_DET']
);
Removing tags
To remove any tags you can use the following sample call. This will drop the Category and Classification tag
call KADA_DEV.KADA_RAW.CREATE_DROP_TAGS(
'DROP',
['CATEGORY','CLASSIFICATION']
);
KADA_METADATA_SNAPSHOT
Use the following procedure to load Snapshot tables of metadata files ingested from KADA via Snowpipe.
This procedure relies on the KADA_METADATA tables mapping between file fields to metadata objects (Tags / Comments / Terms). It uses this to build out the combination of columns to trigger a change. If the combination of tag / comment / term fields contains a change since last ingestion for the PK, then a new record is created and marked with the UPDATE_FLAG set to 'Y'. This is then subsequently used to update tags / comments.
The parameter passed will run the procedure at the table or column level. set to TBL or COL only.
CREATE OR REPLACE PROCEDURE KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT(
    metadata_type STRING -- set to TBL or COL
)
RETURNS VARCHAR
LANGUAGE SQL
AS
$$
DECLARE

    metadata_stream_table VARCHAR;
    metadata_snapshot_table VARCHAR;
    metadata_snapshot_table_tmp VARCHAR;
    metadata_kada VARCHAR;

    tag_fingerprint_res RESULTSET;
    tag_fingerprint_stmt VARCHAR DEFAULT '';
    fingerprint VARCHAR;

    info_schema_col VARCHAR;
    column_list VARCHAR;

    merge_statement VARCHAR;

    info_schema_metadata_table VARCHAR;
    info_schema_res_list RESULTSET;
    info_schema_stmt VARCHAR DEFAULT '';
    info_schema_res_tmp_table RESULTSET;
    info_schema_merge_statement VARCHAR;


BEGIN

    metadata_stream_table := CURRENT_DATABASE()||'.KADA_LANDING.KADA_'||UPPER(:metadata_type)||'_METADATA_STREAM';
    metadata_snapshot_table := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_METADATA_SNAP';
    metadata_snapshot_table_tmp := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_METADATA_SNAP_TMP';
    metadata_kada := CURRENT_DATABASE()||'.KADA_RAW.KADA_METADATA';
    info_schema_col := CURRENT_DATABASE()||'.INFORMATION_SCHEMA.COLUMNS';
    info_schema_metadata_table := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_INFO_SCHEMA_METADATA';


    -----------------------------------------
    --------- SNAPSHOT HASH VALUE
    -----------------------------------------

    --Use tag list to create a hash value of comments/tags to check against in the snapshot
    WITH METADATA_COLUMNS AS (

        select
        'coalesce(cast('|| FILE_COLUMN_NAME ||' as TEXT), ''null_field'')' as METADATA_COLS
        from IDENTIFIER(:metadata_kada) where METADATA_OBJ_LEVEL=:metadata_type

    ) select 'md5(cast(' || LISTAGG(METADATA_COLS, '||') WITHIN GROUP (ORDER BY METADATA_COLS ASC)|| ' as TEXT))' into :fingerprint
    from METADATA_COLUMNS;


    --Get column list of snapshot table from information schema
    select
    LISTAGG(COLUMN_NAME, ', ') WITHIN GROUP (ORDER BY ORDINAL_POSITION) into :column_list
    from IDENTIFIER(:info_schema_col)
    where (TABLE_CATALOG||'.' || TABLE_SCHEMA || '.' || TABLE_NAME) = :metadata_snapshot_table;


    -----------------------------
    --------- SNAP TEMP TABLE
    -----------------------------

    EXECUTE IMMEDIATE '
    create or replace temporary table ' || :metadata_snapshot_table_tmp || ' as (

    with snapshot_query as (

        select
        LOCATION||''/''||UPPER(NAME) AS SNAP_ID,
        (CASE
        WHEN lower(FILE_NAME) like ''%columns_tbl%'' THEN ''TABLE''
        WHEN lower(FILE_NAME) like ''%columns_vw%'' THEN ''VIEW''
        ELSE UPPER(ASSET_SUBTYPE)
        END) AS OBJ_TYPE,
        *, ' || :fingerprint || ' as ROW_CHECK_FINGERPRINT
        from ' || :metadata_stream_table || '
        where METADATA$ACTION =''INSERT''
        QUALIFY row_number() OVER (PARTITION BY SNAP_ID ORDER BY FILE_LAST_MODIFIED DESC) = 1

        ),snapshotted_data as (

            select *, SNAP_ID as snap_unique_key
            from ' || :metadata_snapshot_table || '
            where SNAP_VALID_TO is null

        ), insertions_source_data as (

            select *,
            SNAP_ID as snap_unique_key,
            to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as SNAP_UPDATED_AT,
            to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as SNAP_VALID_FROM,
            coalesce(nullif(to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())), to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp()))), null)
      as SNAP_VALID_TO,
            md5(coalesce(cast(ID as varchar ), '''')
             || ''|'' || coalesce(cast(to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as varchar ), '''')
            ) as SNAP_SCD_ID

            from snapshot_query

        ), updates_source_data as (

            select *, SNAP_ID as snap_unique_key,
            to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as SNAP_UPDATED_AT,
            to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as SNAP_VALID_FROM,
            to_timestamp_ntz(convert_timezone(''UTC'', current_timestamp())) as SNAP_VALID_TO

            from snapshot_query

        ), insertions as (

            select
                ''insert'' as snap_change_type,
                source_data.*

            from insertions_source_data as source_data
            left outer join snapshotted_data
            on snapshotted_data.snap_unique_key = source_data.snap_unique_key
            where snapshotted_data.snap_unique_key is null
            or (snapshotted_data.snap_unique_key is not null and
            ( (snapshotted_data.ROW_CHECK_FINGERPRINT != source_data.ROW_CHECK_FINGERPRINT
            or
            (((snapshotted_data.ROW_CHECK_FINGERPRINT is null) and not (source_data.ROW_CHECK_FINGERPRINT is null))
            or
            ((not snapshotted_data.ROW_CHECK_FINGERPRINT is null) and (source_data.ROW_CHECK_FINGERPRINT is null))))
            ))

        ),updates as (

            select
                ''update'' as snap_change_type,
                source_data.*,
                snapshotted_data.snap_scd_id

            from updates_source_data as source_data
            join snapshotted_data
            on snapshotted_data.snap_unique_key = source_data.snap_unique_key
            where (
            (snapshotted_data.ROW_CHECK_FINGERPRINT != source_data.ROW_CHECK_FINGERPRINT
            or
            (((snapshotted_data.ROW_CHECK_FINGERPRINT is null) and not (source_data.ROW_CHECK_FINGERPRINT is null))
            or ((not snapshotted_data.ROW_CHECK_FINGERPRINT is null) and (source_data.ROW_CHECK_FINGERPRINT is null))
            )))
        )

        select *, NULL AS IS_OBJ_NAME, ''Y'' AS UPDATE_FLAG, NULL AS DELETE_FLAG from insertions
        union all
        select *, NULL AS IS_OBJ_NAME, NULL AS UPDATE_FLAG, NULL AS DELETE_FLAG from updates

     )';


    -----------------------------
    --------- SNAP MERGE
    -----------------------------

    merge_statement := '
        merge into ' || :metadata_snapshot_table || ' as SNAP_INTERNAL_DEST
        using ' || :metadata_snapshot_table_tmp || ' as SNAP_INTERNAL_SOURCE
        on SNAP_INTERNAL_SOURCE.snap_scd_id = SNAP_INTERNAL_DEST.snap_scd_id

        when matched and SNAP_INTERNAL_DEST.snap_valid_to is null
        and SNAP_INTERNAL_SOURCE.snap_change_type in (''update'', ''delete'')
        then update
        set snap_valid_to = SNAP_INTERNAL_SOURCE.snap_valid_to

        when not matched and SNAP_INTERNAL_SOURCE.snap_change_type = ''insert''
        then insert (' ||:column_list|| ')
        values (' ||:column_list|| ')
        ';

    EXECUTE IMMEDIATE :merge_statement;


    -----------------------------------
    --------- CASE SENSITIVE COLUMNS
    -----------------------------------

    IF (:metadata_type = 'COL') THEN

        info_schema_res_list := (

            select
               distinct
                STRTOK(SNAP_ID, '/', 1) as DB
              ,'SELECT TABLE_CATALOG||''/''||TABLE_SCHEMA||''/''||TABLE_NAME||''/''||UPPER(COLUMN_NAME) AS IS_OBJ_LOCATION
              ,COLUMN_NAME AS IS_OBJ_NAME
            FROM '||DB||'.INFORMATION_SCHEMA.COLUMNS WHERE TABLE_SCHEMA<>''INFORMATION_SCHEMA''
            AND (CONTAINS(COLUMN_NAME, '' '') OR REGEXP_LIKE(COLUMN_NAME, ''.*[a-z].*''))'  AS INF_SCHEMA
            from IDENTIFIER(:metadata_snapshot_table)

        );

    ELSE

        info_schema_res_list := (

            select
               distinct
                STRTOK(SNAP_ID, '/', 1) as DB
              ,'SELECT TABLE_CATALOG||''/''||TABLE_SCHEMA||''/''||TABLE_NAME AS IS_OBJ_LOCATION
              ,TABLE_NAME AS IS_OBJ_NAME
            FROM '||DB||'.INFORMATION_SCHEMA.TABLES WHERE TABLE_SCHEMA<>''INFORMATION_SCHEMA''
            AND (CONTAINS(TABLE_NAME, '' '') OR REGEXP_LIKE(TABLE_NAME, ''.*[a-z].*''))'  AS INF_SCHEMA
            from IDENTIFIER(:metadata_snapshot_table)

        );

    END IF;


    FOR info_schema_res_list_record IN info_schema_res_list DO

        IF (:info_schema_stmt = '') THEN
          info_schema_stmt := info_schema_res_list_record.INF_SCHEMA;
        ELSE
          info_schema_stmt := info_schema_stmt || ' UNION ' || info_schema_res_list_record.INF_SCHEMA;
        END IF;

    END FOR;


    info_schema_res_tmp_table := (
            EXECUTE IMMEDIATE '
            create or replace temporary table '||:info_schema_metadata_table||' as
            ' || :info_schema_stmt || ''
    );


    info_schema_merge_statement := '
        merge into ' || :metadata_snapshot_table || ' as SNAP_INTERNAL_DEST
        using ' || :info_schema_metadata_table || ' as SNAP_INTERNAL_SOURCE
        on SNAP_INTERNAL_SOURCE.is_obj_location = SNAP_INTERNAL_DEST.snap_id

        when matched and SNAP_INTERNAL_DEST.snap_valid_to is null
        then update
        set IS_OBJ_NAME = ''"''||SNAP_INTERNAL_SOURCE.IS_OBJ_NAME||''"''
        ';

     EXECUTE IMMEDIATE :info_schema_merge_statement;


  RETURN 'Kada Snapshot Table Updated.';


END;
$$;
Sample calls to be used by the Task or your own processes:
call KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT
(
'TBL'
);

call KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT
(
'COL'
);
KADA_METADATA_SNAPSHOT_CLEANUP
Given that some data extracted from KADA won't match the current state of database objects at the time of export, a cleanup is required on the snapshot table before processing.
-
E.g. a Table is dropped before the Kada to Snowflake sync is completed.
The following procedure updates the column DELETE_FLAG to Y in the snapshot tables where an object (table or column) that exists in the file does not exist in the information schema.
CREATE OR REPLACE PROCEDURE KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT_CLEANUP(
    metadata_type STRING
)
RETURNS VARCHAR
LANGUAGE SQL
AS
$$
DECLARE
    snap_delete_flag_rs RESULTSET;

    metadata_snapshot_table VARCHAR;
    res_info_schema_list RESULTSET;
    info_schema_stmt VARCHAR DEFAULT '';
    info_schema_query VARCHAR;
    info_schema_column VARCHAR;
    info_schema_view VARCHAR;

    snapshot_cleanup_query VARCHAR;
    res_snapshot_cleanup RESULTSET;

BEGIN


    metadata_snapshot_table := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_METADATA_SNAP';


    --clear delete flag
    snap_delete_flag_rs := (EXECUTE IMMEDIATE '
    update ' || :metadata_snapshot_table || '
    SET DELETE_FLAG = NULL'
    );


    IF (:metadata_type = 'COL') THEN
        info_schema_column := '||''.''||COLUMN_NAME';
        info_schema_view := 'COLUMNS';
    ELSE
        info_schema_column := '';
        info_schema_view := 'TABLES';
    END IF;

    res_info_schema_list := (

        select
           distinct
           STRTOK(SNAP_ID, '/', 1) as DB
        , 'SELECT UPPER(TABLE_CATALOG||''.''||TABLE_SCHEMA||''.''||TABLE_NAME' || :info_schema_column || ') AS FQ_LOCATION FROM '||DB||'.INFORMATION_SCHEMA.' || :info_schema_view ||' WHERE TABLE_SCHEMA<>''INFORMATION_SCHEMA''' AS INF_SCHEMA
        from IDENTIFIER(:metadata_snapshot_table)
    );

    FOR res_info_schema_list_record IN res_info_schema_list DO

        IF (:info_schema_stmt = '') THEN
          info_schema_stmt := res_info_schema_list_record.INF_SCHEMA;
        ELSE
          info_schema_stmt := info_schema_stmt || ' UNION ' || res_info_schema_list_record.INF_SCHEMA;
        END IF;

    END FOR;

    --info_schema_query := :info_schema_stmt;

    snapshot_cleanup_query := 'update '||:metadata_snapshot_table||' set DELETE_FLAG = ''Y'' where SNAP_VALID_TO is null
    and REPLACE(UPPER(SNAP_ID), ''/'', ''.'') not in ( ' || :info_schema_stmt || ' ) ';


    res_snapshot_cleanup := (EXECUTE IMMEDIATE :snapshot_cleanup_query);

  RETURN :snapshot_cleanup_query;

END;
$$;
Sample call to run the Cleanup procedure:
CALL KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT_CLEANUP(
    'COL' -- set to TBL or COL
);
KADA_METADATA
The following procedure updates TAGS and COMMENTS at the table or column level
Parameter details:
-
metadata_type: This will run the tag and comment updates either at the table or column level. Fields only to be set are TBL or COL.
-
load_type:
-
INC - This should be the default setting. This runs only against new records loaded to the snapshot table. The column UPDATE_FLAG is set to 'Y' for any new inserts into the snapshot table. When the procedure is run, it filters on this flag column. On completion of the procedure, the flag column is cleared ready for the next run.
-
FULL - This will run tag and comment updates for every table/column in the snapshot table. This can take time to run, particularly at the column level.
-
CATCHUP - This can be run based on an offset for any records that needs to be re-run going back a period of time. This works in conjunction with the parameters “catchup_offset” and catchup_offset_type”.
-
-
catchup_offset: This sets the negative offset of how far back to look. Used only when load_type is set to CATCHUP
-
catchup_offset_type: This sets the type of offset (hour or day) for how far back to look. Used only when load_type is set to CATCHUP.
-
table_list: Enter comma separated fully qualified tables to run procedure against. Can enter one or more tables, or enter ‘ALL’ to run against every table available in the snapshot. This param can also be used to run this procedure in dbt during model runtime to reapply tags and comments when there is a full refresh.
CREATE OR REPLACE PROCEDURE KADA_DEV.KADA_RAW.KADA_METADATA(
    metadata_type STRING, -- set to TBL or COL
    load_type STRING, -- set to FULL or INC
    catchup_offset INT, -- set offset for data to be returned from snapshot
    catchup_offset_type STRING, -- set offset type (day / hour)
    table_list ARRAY -- Fully qualified target table
)
RETURNS VARCHAR
LANGUAGE SQL
AS
$$
DECLARE
    metadata_snapshot_table VARCHAR;
    metadata_tag_location VARCHAR;
    metadata_kada VARCHAR;

    tag_cols VARCHAR;
    tag_names VARCHAR;
    tag_check_null VARCHAR;

    res_comment RESULTSET;
    alter_comment_stmt VARCHAR;
    res_tag RESULTSET;
    alter_tag_stmt VARCHAR;

    snap_filter VARCHAR;
    snap_flag_rs RESULTSET;

    create_terms_table RESULTSET;
    metadata_terms_table VARCHAR;
    metadata_tbl_col_terms_table VARCHAR;


BEGIN

    metadata_snapshot_table :=  CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_METADATA_SNAP';
    metadata_tag_location := CURRENT_DATABASE()||'.TAGS';
    metadata_kada := CURRENT_DATABASE()||'.KADA_RAW.KADA_METADATA';
    metadata_terms_table := CURRENT_DATABASE()||'.KADA_LANDING.KADA_TERM_METADATA';
    metadata_tbl_col_terms_table := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_TERM_METADATA';


    -----------------------------
    --------- FILTER LOGIC
    -----------------------------

    IF (:load_type = 'CATCHUP') THEN
        snap_filter := 'SNAP_UPDATED_AT >= (SELECT dateadd('||:catchup_offset_type||', '||:catchup_offset||', max(SNAP_UPDATED_AT)) FROM '||:metadata_snapshot_table||')';
    ELSEIF (:load_type = 'INC') THEN
        snap_filter := 'UPDATE_FLAG=''Y''';
    ELSE
        snap_filter := '1=1';
    END IF;


    -----------------------------
    --------- TAG LIST
    -----------------------------


    --Use metadata table to build tag columns and check for nulls
    WITH METADATA_COLUMNS AS (

        select
        'nullif(TRIM(' || FILE_COLUMN_NAME || '),'''')' AS TAG_EXPR,
        'nullif(TRIM(' || FILE_COLUMN_NAME || '),'''') AS ' || METADATA_NAME AS TAG_ALIASED,
        METADATA_NAME::VARCHAR AS TAG_NAME
        from IDENTIFIER(:metadata_kada) where METADATA_OBJ_LEVEL=:metadata_type and METADATA_TYPE='TAG'

    ), METADATA_COLUMNS_LIST AS (
        select
        LISTAGG(TAG_EXPR, ', ') WITHIN GROUP (ORDER BY TAG_EXPR ASC) AS TAG_EXPR_LISTAGG,
        LISTAGG(TAG_ALIASED, ', ') WITHIN GROUP (ORDER BY TAG_ALIASED ASC) AS TAG_ALIASED_LISTAGG,
        LISTAGG(TAG_NAME, ', ') WITHIN GROUP (ORDER BY TAG_NAME ASC) AS TAG_NAME_LISTAGG
    from METADATA_COLUMNS GROUP BY ALL
    )
    select
        'COALESCE(' || TAG_EXPR_LISTAGG || ', null)',
        TAG_ALIASED_LISTAGG,
        TAG_NAME_LISTAGG
    INTO :tag_check_null, :tag_cols, :tag_names
    from METADATA_COLUMNS_LIST;


    -----------------------------
    --------- TERMS DATA
    -----------------------------


    create_terms_table := (
        EXECUTE IMMEDIATE '
        create view if not exists '||:metadata_tbl_col_terms_table||' as
        WITH METADATA_SNAPSHOT AS (

            select
              SNAP_ID AS OBJ_ID
            , UPPER(TERMS) AS OBJ_TERMS
            from ' || :metadata_snapshot_table || '
            where NULLIF(TRIM(TERMS), '''') is not null
            and SNAP_VALID_TO is null


        ), LATERAL_SPLIT_TERMS AS (

            select
                MS.OBJ_ID,
                MS.OBJ_TERMS,
                TRIM(SPLIT_TERMS.VALUE) AS OBJ_TERMS_SPLIT
            from METADATA_SNAPSHOT MS,
            LATERAL SPLIT_TO_TABLE(MS.OBJ_TERMS, '','') SPLIT_TERMS

        ), TERMS_METADATA AS (

            select
              TRIM(UPPER(NAME)) AS TERMS
            , REPLACE(DESCRIPTION,'''''','''''''''') AS TERMS_DESCRIPTION
            from '||:metadata_terms_table||'
            where NULLIF(TRIM(TERMS_DESCRIPTION), '''') is not null
            and UPPER(LOCATION) like ''%GLOSSARY%''
            QUALIFY row_number() OVER (PARTITION BY TRIM(UPPER(NAME)), TRIM(UPPER(LOCATION)) ORDER BY FILE_LAST_MODIFIED DESC) = 1

        ), TBL_COL_TERMS_METADATA AS (

            select
            OBJ_ID,
            OBJ_TERMS_SPLIT||'' - ''||TERMS_DESCRIPTION AS OBJ_COMMENT
            from
            LATERAL_SPLIT_TERMS INNER JOIN TERMS_METADATA
            ON LATERAL_SPLIT_TERMS.OBJ_TERMS_SPLIT = TERMS_METADATA.TERMS

        ), TERMS_LISTAGG AS (

                select
                    OBJ_ID,
                    LISTAGG(OBJ_COMMENT, ''\n\n'') WITHIN GROUP (ORDER BY OBJ_COMMENT ASC) AS OBJ_TERMS
                from TBL_COL_TERMS_METADATA
                GROUP BY ALL

        )
        select * from TERMS_LISTAGG

        '
    );


    -----------------------------
    --------- COMMENT UPDATE
    -----------------------------


        res_comment := (
            EXECUTE IMMEDIATE '
                WITH KADA_METADATA_SNAP AS (
                    select
                      SNAP_ID AS OBJ_ID
                    , CONCAT_WS(''.'', STRTOK(SNAP_ID, ''/'', 1), STRTOK(SNAP_ID, ''/'', 2), STRTOK(SNAP_ID, ''/'', 3) ) AS OBJ_LOCATION
                    , OBJ_TYPE
                    , NVL(IS_OBJ_NAME,UPPER(NAME)) AS OBJ_NAME
                    , IFNULL(REPLACE(DESCRIPTION,'''''''',''''''''''''),'''') AS OBJ_DESC
                    --, NVL2(OBJ_DESC, ''DESCRIPTION - ''||OBJ_DESC, '''') AS OBJ_COMMENT
                    from ' || :metadata_snapshot_table || '
                    where LOCATION is not null and SNAP_VALID_TO is null and DELETE_FLAG is null
                    AND ' || :snap_filter || '
                    AND (
                    OBJ_LOCATION in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
                    OR ''ALL'' in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
                    )
                )
                select
                  MS.OBJ_ID
                , MS.OBJ_LOCATION
                , MS.OBJ_NAME
                , MS.OBJ_TYPE
                , IFNULL(REPLACE(TM.OBJ_TERMS,'''''''',''''''''''''),'''') AS OBJ_TERMS_TM
                , (CASE WHEN (MS.OBJ_DESC='''' or OBJ_TERMS_TM='''') THEN '''' ELSE ''\n\n'' END) AS LB
                , MS.OBJ_DESC||LB||OBJ_TERMS_TM AS OBJ_COMMENT
                from KADA_METADATA_SNAP MS
                LEFT JOIN
                ' || :metadata_tbl_col_terms_table || ' TM
                ON MS.OBJ_ID=TM.OBJ_ID
                where (MS.OBJ_DESC<>'''' or OBJ_TERMS_TM<>'''')
            '
        );


        FOR comment_record IN res_comment DO

            IF (:metadata_type = 'TBL') THEN
                alter_comment_stmt := 'ALTER ' || comment_record.OBJ_TYPE || ' ' || comment_record.OBJ_LOCATION || ' SET  COMMENT= '''|| comment_record.OBJ_COMMENT ||'''';
            ELSE
                alter_comment_stmt := 'ALTER ' || comment_record.OBJ_TYPE || ' ' || comment_record.OBJ_LOCATION || ' MODIFY COLUMN ' || comment_record.OBJ_NAME || ' COMMENT '''|| comment_record.OBJ_COMMENT ||'''';
            END If;

            ASYNC (EXECUTE IMMEDIATE :alter_comment_stmt);

        END FOR;

        AWAIT ALL;


    -----------------------------
    --------- TAG UPDATE
    -----------------------------


        res_tag :=  (
        EXECUTE IMMEDIATE '

          WITH TAG_QUERY AS (

            select
                CONCAT_WS(''.'', STRTOK(SNAP_ID, ''/'', 1), STRTOK(SNAP_ID, ''/'', 2), STRTOK(SNAP_ID, ''/'', 3) ) AS OBJ_LOCATION
              , NVL(IS_OBJ_NAME,UPPER(NAME)) AS OBJ_NAME
              , OBJ_TYPE
              , ' || :tag_cols || '
              , ' || :tag_check_null || ' AS TAGS
              , ''' || :metadata_tag_location || ''' AS TAG_LOCATION
            from ' || :metadata_snapshot_table || '
            where TAGS IS NOT NULL and LOCATION is not null and SNAP_VALID_TO is null and DELETE_FLAG is null
            AND ' || :snap_filter || '
            AND (
            OBJ_LOCATION in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
            OR ''ALL'' in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
            )

        ), UNPIVOT_TAG AS (

            select * from TAG_QUERY
            unpivot  EXCLUDE NULLS (tag_val for TAG_COL in (' || :tag_names || '))
            order by 2

        ), LIST_AGG AS (

            SELECT OBJ_LOCATION, OBJ_NAME, OBJ_TYPE, TAG_LOCATION, LISTAGG(TAG_LOCATION||''.''||TAG_COL||''=''''''||REPLACE(TAG_VAL,'''''''','''''''''''')||'''''''', '', '') WITHIN GROUP (ORDER BY OBJ_NAME) AS TAGS_VAL
            FROM UNPIVOT_TAG
            GROUP BY ALL

        ) select * from LIST_AGG

        ');


           FOR tag_record IN res_tag DO

            IF (:metadata_type = 'TBL') THEN
                alter_tag_stmt := 'ALTER ' || tag_record.OBJ_TYPE || ' ' || tag_record.OBJ_LOCATION || ' SET TAG '||tag_record.TAGS_VAL||'';
            ELSE
                alter_tag_stmt := 'ALTER ' || tag_record.OBJ_TYPE || ' ' || tag_record.OBJ_LOCATION || ' MODIFY COLUMN ' || tag_record.OBJ_NAME || ' SET TAG '||tag_record.TAGS_VAL||'';
            END If;

            ASYNC (EXECUTE IMMEDIATE :alter_tag_stmt);

        END FOR;

        AWAIT ALL;


    -----------------------------
    --------- FLAG UPDATE
    -----------------------------

    IF (:load_type = 'INC') THEN
        snap_flag_rs := (EXECUTE IMMEDIATE '
        update ' || :metadata_snapshot_table || '
        SET  UPDATE_FLAG = NULL'
        );
    END IF;


  RETURN 'TAG and COMMENT Updates Completed';
  --RETURN table(res_tag);


END;
$$;
Sample calls:
--Table level. Runs for any new records in the snapshot table where the Update flag = Y and for all tables
CALL KADA_DEV.KADA_RAW.KADA_METADATA(
    'TBL',  -- set to TBL or COL
    'INC',  -- set to FULL or INC or CATCHUP
    -1,     -- set offset for data to be returned from snapshot
    'hour',  -- set offset type (day / hour) for data to be returned from snapshot
    ['ALL']
);

--Table level. Runs for any records where the SNAP_UPDATED_AT is greater than the specified offset params (-1 hour from the max SNAP_UPDATED_AT datetime)
CALL KADA_DEV.KADA_RAW.KADA_METADATA(
    'TBL',  -- set to TBL or COL
    'CATCHUP',  -- set to FULL or INC or CATCHUP
    -1,     -- set offset for data to be returned from snapshot
    'hour',  -- set offset type (day / hour) for data to be returned from snapshot
    ['ALL']
);

--Column level. Runs for two tables listed in the array. It will run all available tags and comments in the snapshot for these tables.
CALL KADA_DEV.KADA_RAW.KADA_METADATA(
    'COL',  -- set to TBL or COL
    'FULL',  -- set to FULL or INC or CATCHUP
    -1,     -- set offset for data to be returned from snapshot
    'hour',  -- set offset type (day / hour) for data to be returned from snapshot
    ['COMMON_DEV.DWH_GOLD.DIM_B2B_CONTACT','COMMON_DEV.DWH_GOLD.DIM_SITE_MRF']
);


--Table level. Updates the tags and comment for a singel table. This setting can be used during a dbt model run, called from a macro.
CALL KADA_DEV.KADA_RAW.KADA_METADATA(
    'TBL',  -- set to TBL or COL
    'FULL',  -- set to FULL or INC or CATCHUP
    -1,     -- set offset for data to be returned from snapshot
    'hour',  -- set offset type (day / hour) for data to be returned from snapshot
    ['COMMON_DEV.DWH_GOLD.DIM_SITE_MRF']
);
Bringing it all together
Use Snowflake tasks to run the comment and tag updates.
Each task only gets triggered when new data is detected in a stream. They can also be scheduled or triggered by a separate process.
The tasks run 3 procedures as outlined below.
The KADA_METADATA procedure in each task should only pass by default the parameter “INC” for the load_type and “ALL” for the table_list. This ensures the procedure will only process new records where the UPDATE_FLAG is set to “Y” and for all tables.
--TASK FOR TABLE LEVEL UPDATES

CREATE OR REPLACE TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK
    WAREHOUSE = [WAREHOUSE_NAME]
    WHEN SYSTEM$STREAM_HAS_DATA('KADA_DEV.KADA_LANDING.KADA_TBL_METADATA_STREAM')
AS
BEGIN

    --Updates snapshot table based on stream data received from snowpipe ingestion
    call KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT
    (
    'TBL'  -- set to TBL for table level snapshot table
    );

    --Snapshot Cleanup
    CALL KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT_CLEANUP(
        'TBL' -- set to TBL or COL
    );

    --Updates tags/comments
    --if using the dbt procedure to update tags/comments, this can be removed from the task
    CALL KADA_DEV.KADA_RAW.KADA_METADATA(
        'TBL',  -- set to TBL or COL
        'INC',  -- set to INC by default (FULL/INC/CATCHUP)
        -1,     -- set offset for data to be returned from snapshot
        'hour', -- set offset type (day / hour) for data to be returned from snapshot4
        ['ALL']  -- All tables
    );


END;


--TASK FOR COLUMN LEVEL UPDATES

CREATE OR REPLACE TASK KADA_DEV.KADA_RAW.KADA_COL_METADATA_TASK
    WAREHOUSE = [WAREHOUSE_NAME]
    WHEN SYSTEM$STREAM_HAS_DATA('KADA_DEV.KADA_LANDING.KADA_COL_METADATA_STREAM')
AS
BEGIN

    --Updates snapshot table based on stream data received from snowpipe ingestion
    call KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT
    (
    'COL' -- set to COL for table level snapshot table
    );

    --Snapshot Cleanup
    CALL KADA_DEV.KADA_RAW.KADA_METADATA_SNAPSHOT_CLEANUP(
        'COL' -- set to TBL or COL
    );

    --Updates tags/comments
    --if using the dbt procedure to update tags/comments, this can be removed from the task
    CALL KADA_DEV.KADA_RAW.KADA_METADATA(
        'COL',  -- set to TBL or COL
        'INC',  -- set to INC by default (FULL/INC/CATCHUP)
        -1,     -- set offset for data to be returned from snapshot
        'hour',  -- set offset type (day / hour) for data to be returned from snapshot
        ['ALL'] -- All tables
    );

END;

--If running procs manually, the tasks can be suspended and then resumed:
ALTER TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK SUSPEND;
ALTER TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK RESUME;

show tasks in database kada_dev;

--View task history
SELECT *
FROM TABLE(kada_dev.information_schema.task_history(
  task_name => 'KADA_TBL_METADATA_TASK'
))
ORDER BY scheduled_time DESC;
When initially created, the tasks are in a suspended state. To start them, run the alter statement to resume,
NOTE: Prior to enabling the tasks, end to end testing should be carried out to ensure files are ingested correctly and each procedure runs without issue. Each procedure can be run manually to validate tags and comments are updated.
ALTER TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK RESUME;
ALTER TASK KADA_DEV.KADA_RAW.KADA_COL_METADATA_TASK RESUME;
Change management
If you want to add a new tag to the metadata sync, you will need to
-
Suspend the task
-
Update the K extract with the new field
-
Create new tag in the Kada database
-
Add new tag entry to the KADA_METADATA control table
-
Alter snapshot table with new column
-
Resume task
The following describes the above steps in detail:
When a file arrives with a new column, the Snowpipe landing table automatically adds this new column since schema evolution has been enabled.
The new column will adopt the name of the column received from the file. Schema evolution is based on column name matching. The column will be appended to the end of the landing table.
Existing Process when a new column is added
When a new tag column is added to the landing table, the procedures to load the snapshot table and updating tags/comments will continue to run as though the new tag column doesnt exist. This ensures continuity of process in the event of a change and to control what tags are introduced to environments.
The new column will continue to be loaded to the landing table from snowpipe, but in order for this tag to be applied, downstream updates are required to accommodate the new tag.
Suspend Task
ALTER TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK SUSPEND;
Create new tag in database
The CREATE_DROP_TAGS procedure can be used to create the new tag in the target environment. Without creating this, the tag cannot be assigned to tables/columns.
Ensure the tag name matches the name entered in the KADA_METADATA table.
call KADA_DEV.KADA_RAW.CREATE_DROP_TAGS(
'CREATE',
['NEW_TAG']
);
Alter snapshot table with new column
The snapshot table needs to be altered to add the required column.
ALTER TABLE KADA_DEV.KADA_RAW.KADA_TBL_METADATA_SNAP ADD COLUMN NEW_TAG VARCHAR(16777216);
Ensure the column name matches the column name loaded to the snowpipe landing table.
Add new tag entry to the KADA_METADATA table
The KADA_METADATA table is a manually maintained table mapping file field names to tag and comment objects.
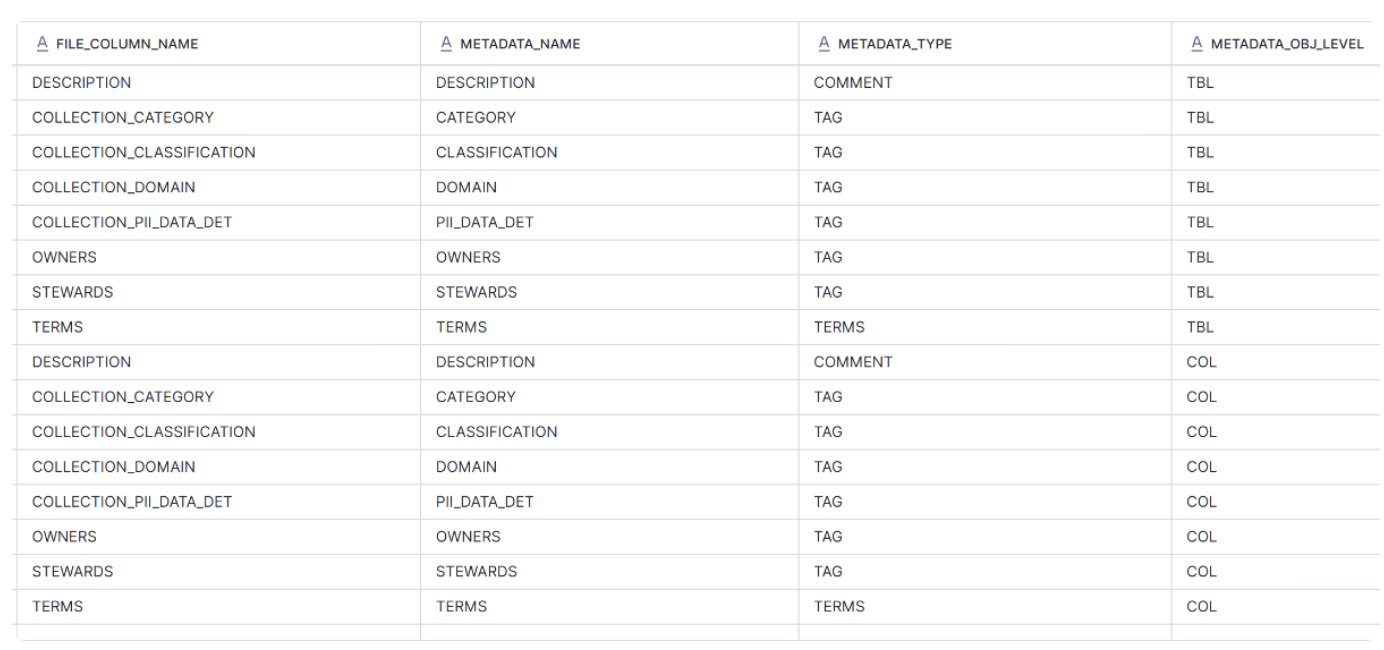
Fields include:
FILE_COLUMN_NAME - Column name as received from the file
METADATA_NAME - The naming convention to be used for tags/comments
METADATA_TYPE - The metadata type, tag / comment / term
METADATA_OBJ_LEVEL - The object level at which the tag / comment is applied. This can allow for different tags to be applied at the table level compared to the column level.
Apply an insert for the new tag.
Once the new entry is in the table, this will be picked up on the next run and included as part of the trigger to detect a new snapshot record for each table, and run tag/comment updates on this new tag.
NOTE: Since a new tag will be included to trigger a new record, initially all records in the snapshot will create a new record since the combination of tags / comments / terms will change for every record. Based on this, the UPDATE_FLAG would be set to “Y” for all records. After this change is in place, it will run the tag / comment update as if its a full refresh. Subsequent to this, normal incremental runs will continue.
Resume Task
ALTER TASK KADA_DEV.KADA_RAW.KADA_TBL_METADATA_TASK RESUME;
Operational tasks
UNSET_TAGS_COMMENTS
This procedure unsets tags or comments that have been applied. This is a manually run procedure if tags or comments need to be removed.
Parameter details:
-
metadata_type: This will run the tag and comment updates either at the table or column level. Fields only to be set are TBL or COL.
-
unset_type: Set this to TAG or COMMENT.
-
tag_list: Enter a comma separated list of tags to unset. This only applies when the unset_type is set to TAG. Enter at least one tag.
-
table_list: Enter comma separated fully qualified tables to run procedure against. Can enter one or more tables, or enter ‘ALL’ to run against every table available in the snapshot.
Note: The snowflake TAG_REFERENCES table could also be used to determine what tags are set but did not use this as there is a lag when this table gets updated. If tags get applied that require an unset, this table cant immediately be used.
CREATE OR REPLACE PROCEDURE KADA_DEV.KADA_RAW.UNSET_TAGS_COMMENTS(
    metadata_type STRING, -- set to TBL or COL
    unset_type STRING, -- COMMENT or TAG
    tag_list ARRAY, -- set List of Tags
    table_list ARRAY -- set tables to unset or ALL
)
RETURNS VARCHAR
LANGUAGE SQL
AS
$$
DECLARE
    metadata_snapshot_table VARCHAR;
    metadata_tag_location VARCHAR;
    metadata_kada VARCHAR;

    tag_cols VARCHAR;
    tag_names VARCHAR DEFAULT '';
    tag_check_null VARCHAR;

    res_comment RESULTSET;
    res_tag RESULTSET;

    metadata_tbl_col_terms_table VARCHAR;

    unset_comment_stmt VARCHAR;
    unset_tag_stmt VARCHAR;


BEGIN

    metadata_snapshot_table :=  CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_METADATA_SNAP';
    metadata_tag_location := CURRENT_DATABASE()||'.TAGS';
    metadata_tbl_col_terms_table := CURRENT_DATABASE()||'.KADA_RAW.KADA_'||UPPER(:metadata_type)||'_TERM_METADATA';
    metadata_kada := CURRENT_DATABASE()||'.KADA_RAW.KADA_METADATA';


    -----------------------------
    --------- TAG LIST
    -----------------------------

    --Use metadata table to build tag columns and check for nulls
    WITH METADATA_COLUMNS AS (
        select
        'nullif(TRIM(' || FILE_COLUMN_NAME || '),'''')' AS TAG_EXPR,
        'nullif(TRIM(' || FILE_COLUMN_NAME || '),'''') AS ' || METADATA_NAME AS TAG_ALIASED,
        METADATA_NAME::VARCHAR AS TAG_NAME
        from IDENTIFIER(:metadata_kada) where METADATA_OBJ_LEVEL=:metadata_type and METADATA_TYPE='TAG'
        and METADATA_NAME in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => :tag_list)))
    ), METADATA_COLUMNS_LIST AS (
        select
        LISTAGG(TAG_EXPR, ', ') WITHIN GROUP (ORDER BY TAG_EXPR ASC) AS TAG_EXPR_LISTAGG,
        LISTAGG(TAG_ALIASED, ', ') WITHIN GROUP (ORDER BY TAG_ALIASED ASC) AS TAG_ALIASED_LISTAGG,
        LISTAGG(TAG_NAME, ', ') WITHIN GROUP (ORDER BY TAG_NAME ASC) AS TAG_NAME_LISTAGG
    from METADATA_COLUMNS GROUP BY ALL
    )
    select
        'COALESCE(' || TAG_EXPR_LISTAGG || ', null)',
        TAG_ALIASED_LISTAGG,
        TAG_NAME_LISTAGG
    INTO :tag_check_null, :tag_cols, :tag_names
    from METADATA_COLUMNS_LIST;


    IF (:unset_type = 'COMMENT') THEN


    -----------------------------
    --------- COMMENT UNSET
    -----------------------------


        res_comment := (
            EXECUTE IMMEDIATE '
                WITH KADA_METADATA_SNAP AS (
                    select
                      SNAP_ID AS OBJ_ID
                    , CONCAT_WS(''.'', STRTOK(SNAP_ID, ''/'', 1), STRTOK(SNAP_ID, ''/'', 2), STRTOK(SNAP_ID, ''/'', 3) ) AS OBJ_LOCATION
					, OBJ_TYPE
                    , NVL(IS_OBJ_NAME,UPPER(NAME)) AS OBJ_NAME
                    , IFNULL(REPLACE(DESCRIPTION,'''''''',''''''''''''),'''') AS OBJ_DESC
                    --, NVL2(OBJ_DESC, ''DESCRIPTION - ''||OBJ_DESC, '''') AS OBJ_COMMENT
                    from ' || :metadata_snapshot_table || '
                    where LOCATION is not null and SNAP_VALID_TO is null
                    AND (
                    OBJ_LOCATION in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
                    OR ''ALL'' in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
                    )
                )
                select
                  MS.OBJ_ID
                , MS.OBJ_LOCATION
                , MS.OBJ_NAME
				, MS.OBJ_TYPE
                , IFNULL(REPLACE(TM.OBJ_TERMS,'''''''',''''''''''''),'''') AS OBJ_TERMS_TM
                , (CASE WHEN (MS.OBJ_DESC='''' or OBJ_TERMS_TM='''') THEN '''' ELSE ''\n\n'' END) AS LB
                , MS.OBJ_DESC||LB||OBJ_TERMS_TM AS OBJ_COMMENT
                ,(CASE WHEN ''' ||:metadata_type|| '''=''TBL'' THEN
                ''ALTER ''||OBJ_TYPE||'' ''||OBJ_LOCATION||'' UNSET COMMENT;''
                ELSE
                ''ALTER ''||OBJ_TYPE||'' ''||OBJ_LOCATION||'' MODIFY COLUMN ''||OBJ_NAME||'' UNSET COMMENT;''
                END) OBJ_UNSET
                from KADA_METADATA_SNAP MS
                LEFT JOIN
                ' || :metadata_tbl_col_terms_table || ' TM
                ON MS.OBJ_ID=TM.OBJ_ID
                where (MS.OBJ_DESC<>'''' or OBJ_TERMS_TM<>'''')
            '
        );


        FOR comment_record IN res_comment DO

            unset_comment_stmt := comment_record.OBJ_UNSET;

            ASYNC (EXECUTE IMMEDIATE :unset_comment_stmt);

        END FOR;

        AWAIT ALL;


    ELSE

    -----------------------------
    --------- TAG UPDATE
    -----------------------------


        res_tag :=  (
        EXECUTE IMMEDIATE '

          WITH TAG_QUERY AS (

            select
                CONCAT_WS(''.'', STRTOK(SNAP_ID, ''/'', 1), STRTOK(SNAP_ID, ''/'', 2), STRTOK(SNAP_ID, ''/'', 3) ) AS OBJ_LOCATION
              , NVL(IS_OBJ_NAME,UPPER(NAME)) AS OBJ_NAME
			  , OBJ_TYPE
              , ' || :tag_cols || '
              , ' || :tag_check_null || ' AS TAGS
              , ''' || :metadata_tag_location || ''' AS TAG_LOCATION
            from ' || :metadata_snapshot_table || '
            where TAGS IS NOT NULL and LOCATION is not null and SNAP_VALID_TO is null
            AND (
            OBJ_LOCATION in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
            OR ''ALL'' in (SELECT VALUE FROM TABLE(FLATTEN(INPUT => PARSE_JSON(''' || :table_list::VARCHAR || '''))))
            )

        ), UNPIVOT_TAG AS (

            select * from TAG_QUERY
            unpivot  EXCLUDE NULLS (tag_val for TAG_COL in (' || :tag_names || '))
            order by 2

        ), LIST_AGG AS (

            SELECT OBJ_LOCATION, OBJ_NAME, OBJ_TYPE, TAG_LOCATION,
            LISTAGG(TAG_LOCATION||''.''||TAG_COL, '', '') WITHIN GROUP (ORDER BY OBJ_NAME) AS TAGS_VAL
            FROM UNPIVOT_TAG
            GROUP BY ALL

        ) select
            *,
            (CASE WHEN ''' ||:metadata_type|| '''=''TBL'' THEN
            ''ALTER ''||OBJ_TYPE||'' ''||OBJ_LOCATION||'' UNSET TAG ''||TAGS_VAL||'';''
            ELSE
            ''ALTER ''||OBJ_TYPE||'' ''||OBJ_LOCATION||'' MODIFY COLUMN ''||OBJ_NAME||'' UNSET TAG ''||TAGS_VAL||'';''
            END) OBJ_UNSET

          from LIST_AGG

        ');


        FOR res_tag_record IN res_tag DO

            unset_tag_stmt := res_tag_record.OBJ_UNSET;

            ASYNC (EXECUTE IMMEDIATE :unset_tag_stmt);

        END FOR;

        AWAIT ALL;


    END IF;


  RETURN 'Unset Complete';


END;
$$;
Sample call:
CALL KADA_DEV.KADA_RAW.UNSET_TAGS_COMMENTS(
    'TBL',  -- set to TBL or COL
    'COMMENT', -- Unset type COMMENT or TAG
    ['CATEGORY','CLASSIFICATION', 'DOMAIN', 'OWNERS', 'STEWARDS', 'PII_DATA_DET'], -- List of Tags to be Unset
    ['COMMON_DEV.DWH_GOLD.FACT_GL_JOURNAL','COMMON_DEV.DWH.CRP_SITE_HOURS'] -- List of tables
);
Post hook with DBT
In DBT, use a macro to call the KADA_METADATA procedure. This allows you to sync metadata where DBT has recreated the table and dropped all the metadata.
It is assumed the target values in DBT are set to DEV / UAT or PROD in their respective environments in order to correctly pass the target.name value to the macro.
{% macro kada_metadata_update(metadata_type, target_table) %}

    {% set procedure_database = 'KADA_'~ target.name|upper %}

    {% set query %}
        CALL {{ procedure_database }}.KADA_RAW.KADA_METADATA('{{ metadata_type }}', 'FULL', -1, 'hour', ['{{ target_table }}'])
    {% endset %}

    {% do run_query(query) %}

{% endmacro %}
The following is a sample post hook applied to a dbt model. There are two procedure calls to run at the table and column level. “this” passes the fully qualified target table.
{{ config(
    post_hook=[
        "{{ kada_metadata_update('TBL', this) }}",
        "{{ kada_metadata_update('COL', this) }}"
    ]
)
}}
Limitations
-
If for example a TABLE was dropped and subsequently created as a VIEW in the same Database and Schema, and the name of the view was the same as the dropped table, then this would not trigger a new record in the snapshot table. This edge case is under review.